An AI harness for game development is the control layer that connects a language or reinforcement agent to your game engine so it can observe state, act, and be evaluated without destabilizing the build—this is the single most important infrastructure decision before you attempt agentic playtesting, balance tuning, or NPC behavior generation.
What an AI Harness Actually Does
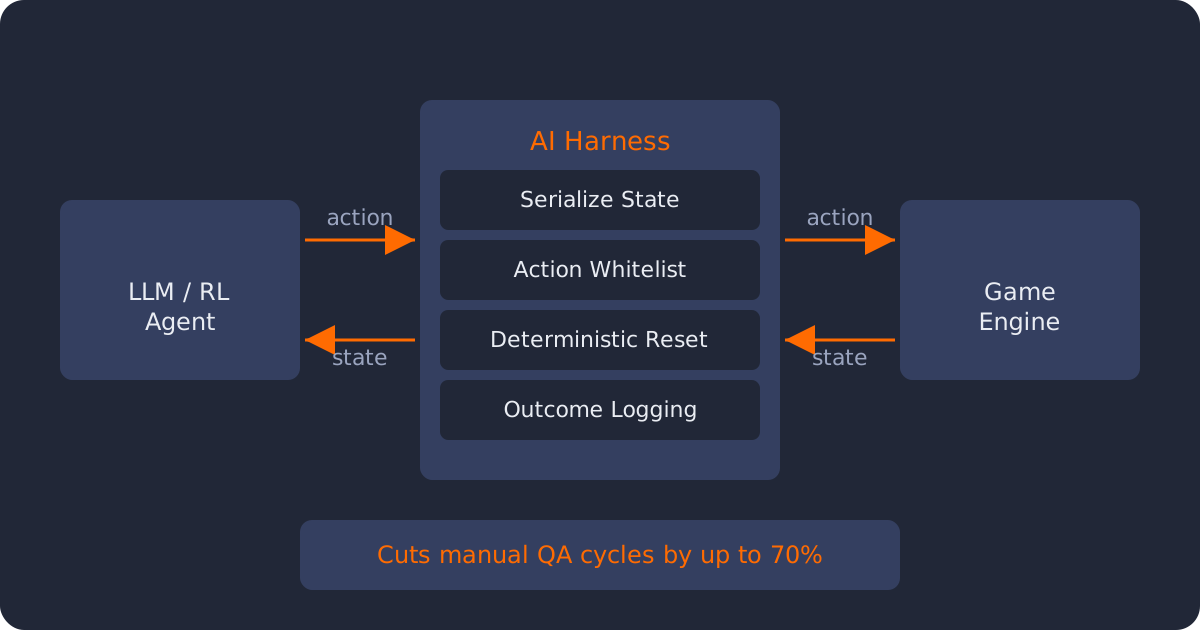
A harness is not the agent itself. It’s the middleware that:
- Serializes game state into a format the model can consume (JSON snapshots, screenshot buffers, or symbolic feature vectors)
- Exposes a constrained action API so the agent can’t call arbitrary engine functions
- Enforces determinism via seeded resets, so runs are reproducible for debugging and evaluation
- Logs outcomes separately from rewards, so you can audit why an agent made a decision, not just what score it got
Without this layer, agents either hallucinate invalid moves, crash the engine, or produce unverifiable results.
Core Components
class GameHarness:
    def __init__(self, engine_adapter, action_whitelist, max_steps=500):
        self.engine = engine_adapter
        self.whitelist = action_whitelist
        self.max_steps = max_steps
        self.step_count = 0

    def reset(self, seed: int):
        self.step_count = 0
        return self.engine.load_state(seed=seed)

    def step(self, action: str, params: dict):
        if action not in self.whitelist:
            raise ValueError(f"Rejected unsanctioned action: {action}")
        self.step_count += 1
        obs = self.engine.apply_action(action, params)
        done = self.step_count >= self.max_steps or self.engine.is_terminal()
        return obs, done, self._log(action, obs)

    def _log(self, action, obs):
        return {"step": self.step_count, "action": action, "state_hash": hash(str(obs))}
This minimal pattern enforces three non-negotiables: a hard step ceiling, an action whitelist, and per-step logging with a hashable state fingerprint for diffing runs.
Choosing Your Interface Layer
| Approach | Latency | Determinism | Best For |
|---|---|---|---|
| Direct engine API hooks (Unity ML-Agents, Godot GDExtension) | Low | High | Production playtest bots, RL training |
| Screen-pixel + vision model input | High | Low–Medium | Prototyping, no-engine-access testing |
| Memory-mapped state export (custom JSON bridge) | Medium | High | Turn-based or grid games, balance simulation |
| Full engine fork with instrumented hooks | Low | Very High | Long-running agent training pipelines |
For most studios, a memory-mapped JSON bridge offers the best cost-to-reliability ratio—no engine fork required, and state is fully inspectable.
Guardrails That Prevent Agent Drift
- Action whitelisting, not prompt-based restriction—validate server-side, never trust the model’s output alone.
- Step and token budgets per episode to cap runaway loops and API cost.
- Separate evaluation harness from training harness—agents optimizing against their own eval loop will overfit to it.
- Replay logging with state hashes so any regression can be reproduced bit-for-bit.
- Kill switch at the engine adapter level, independent of the agent’s own exit logic.
Common Failure Modes
- Non-deterministic physics breaking reproducibility—fix with fixed-timestep simulation during harness runs.
- Action space too large, causing the agent to waste steps exploring invalid commands—start with a minimal viable action set and expand incrementally.
- Reward hacking when harness and reward signal share the same state reader—keep reward computation in a separate, read-only process.
Bottom Line
Build the harness before you build the agent. A constrained, deterministic, logged interface is what turns an LLM from a chat tool into a reliable game-testing or NPC-driving system—skipping it leads to unreproducible bugs and wasted compute on unverifiable agent behavior.